When an agent says "done" and the task isn't, a June 2026 paper calls it false success. In the airline and retail domains of the tau2-bench customer-service benchmark, it was 45% and 48% of all agent failures (Advani, June 2026). So I read the source of 18 of the most-installed AI agent frameworks at a fixed commit (23 October), from LangChain, LlamaIndex and CrewAI to OpenAI's Agents SDK, Google's ADK and Vercel's AI SDK.
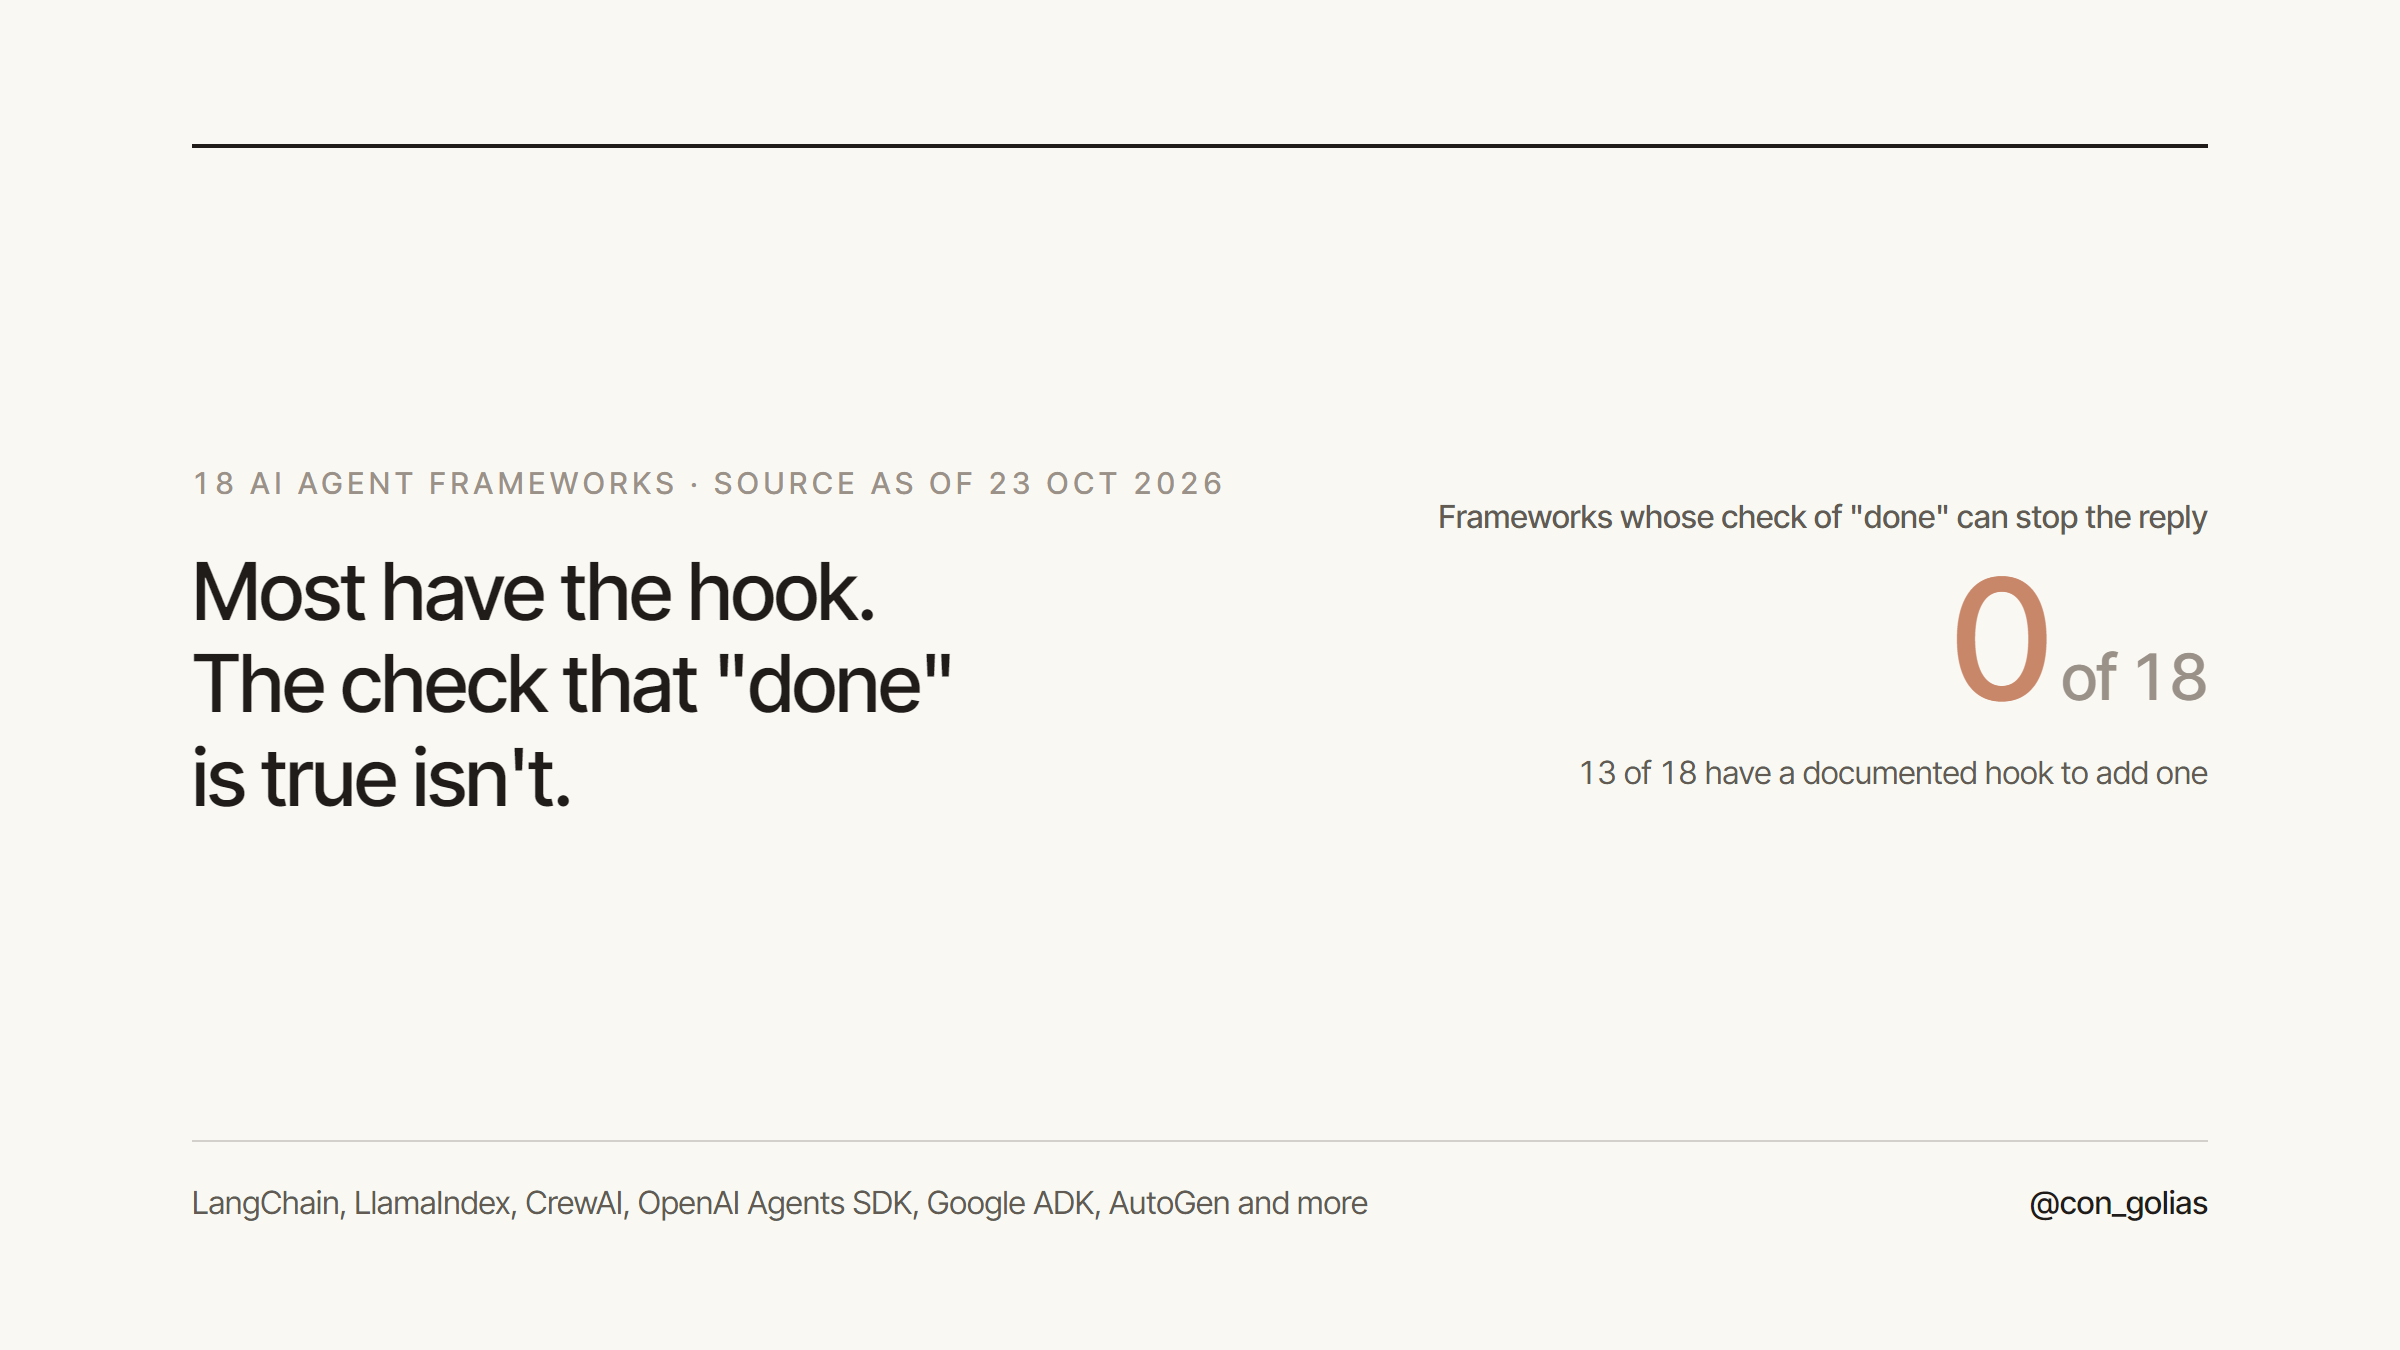
13 of 18 have a documented hook on the final reply that can block or change it, and 11 of those 13 let the hook see what the tools returned.
0 of 18 ship a check that compares the reply's "done" with the tools' real results and can stop the reply.
The checks that do compare claims with tools run as evaluations or in the background. They measure afterwards; they don't gate.
That is a defensible design choice, not a scandal. Most of them give you the hook. The check is yours to write.
What I took from it as a builder: if your agent talks to customers, put a check in that hook that holds any "done" the tool results don't back. And read what "blocked" means in your framework. In at least one, a failed check marks the run as an error but leaves the text in the returned object.
Full evidence, file by file, in the X Article (24 Oct): https://x.com/con_golias/status/2113958660284006570