Scale AI shipped a repaired SWE-Bench Pro in September, and on it Claude Code with Opus 5 resolves 99.4% of the 642 tasks. When the benchmark launched in September 2025, the best model solved 23% of the original set. I wanted to know what the agent is handed, so I opened all 731 original tasks and all 642 repaired ones and compared the prompt with the hidden tests.
In 353 of the 731 original tasks (48%), the hidden tests call a new function, class or field the agent has to create. In SWE-bench Verified it is 19 of 500.
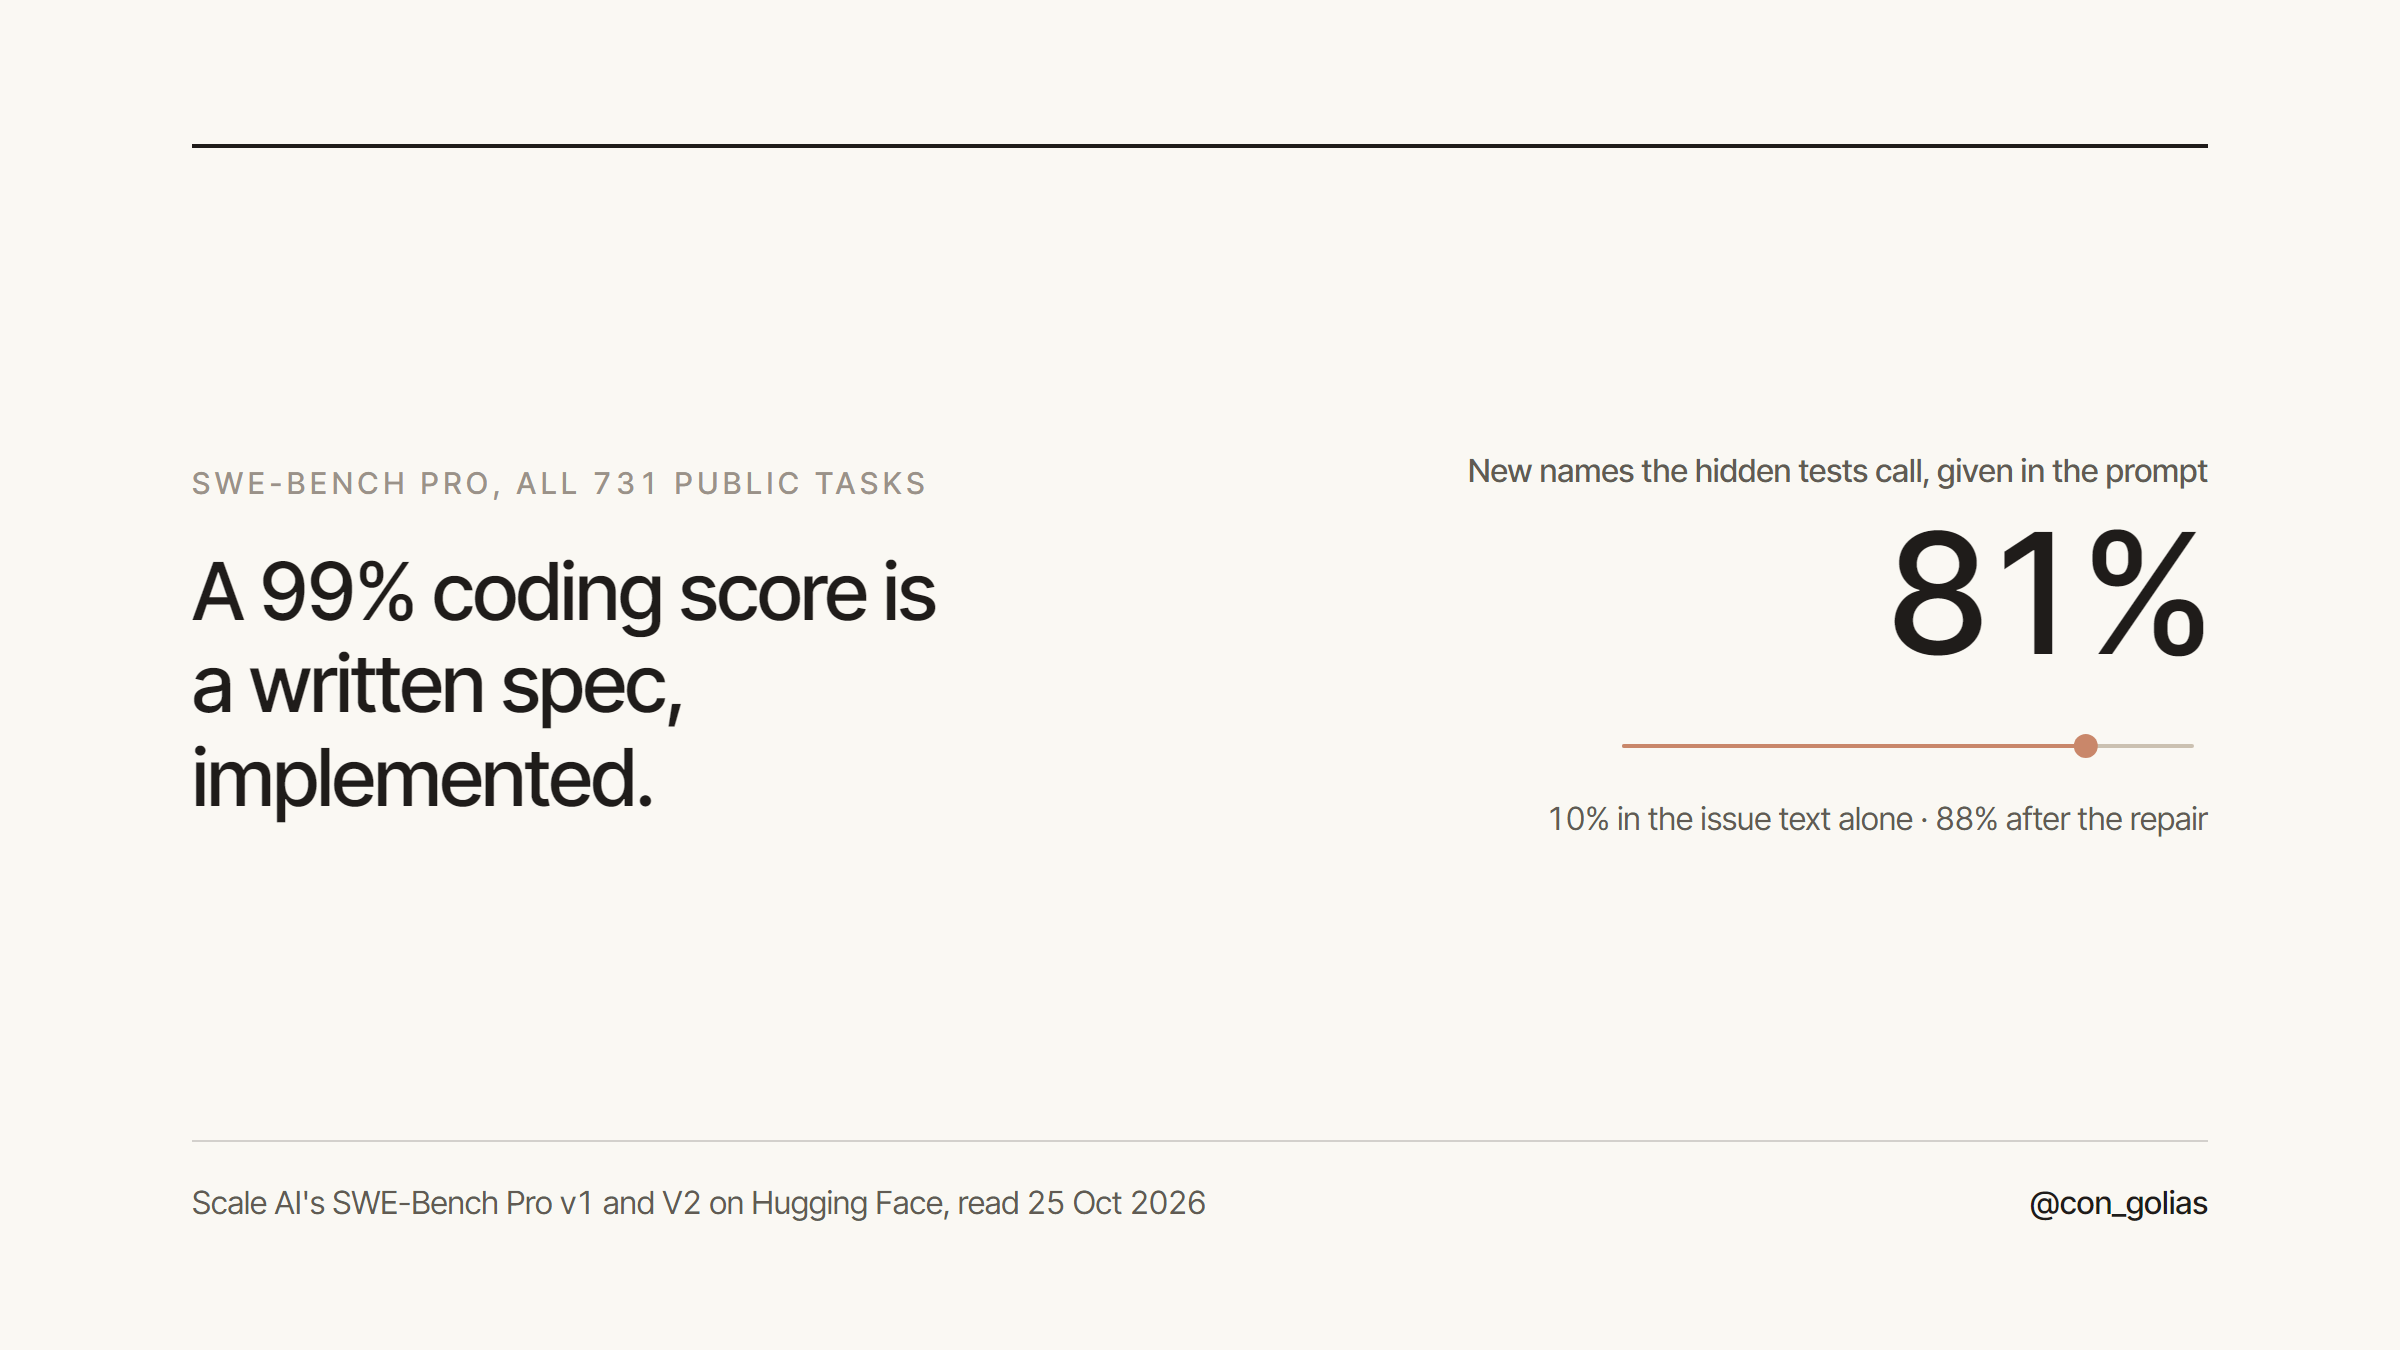
The issue text names 10% of those new names. The full prompt, with the "requirements" and "interface" fields Scale added, names 81%. In the repaired version, 88%.
Scale added those fields for a sound reason: without them, a correct fix with a different name fails the tests.
What I took from it as a builder: a 99% here is the score of an agent implementing a specification a person wrote. Write your own agent's tasks the way Scale writes them: name the functions your tests will call, quote any message that will be compared, and keep the design decision for yourself, because that is the part to review hardest.
Full method and data in the X Article: https://x.com/con_golias/status/2114495930074325295